PDF Document Extraction Engine - Next.js Boilerplate
- Category
- Boilerplate
- Tech stack
- Framework: Next.js (App Router), AI Integration: Vercel AI SDK 7, Validation: Zod, PDF Parsing: pdf2json, Styling: Tailwind CSS
- Price
- $69.00 USD
- Quality grade
- Not yet scored
- Seller
- Aditya
- License
- Commercial use included
- Delivery
- Repo access
- Updated
- 7 Nov 2026
Description
Product Name: PDF Document Extraction Engine - Next.js Boilerplate
Tagline: A Map-Reduce Next.js starter kit that parses massive PDFs into structured JSON without hitting token limits or 502 timeouts.
Description: Building AI document extraction from scratch usually means spending weekends fighting output truncation, Next.js server timeouts, and API rate limits.
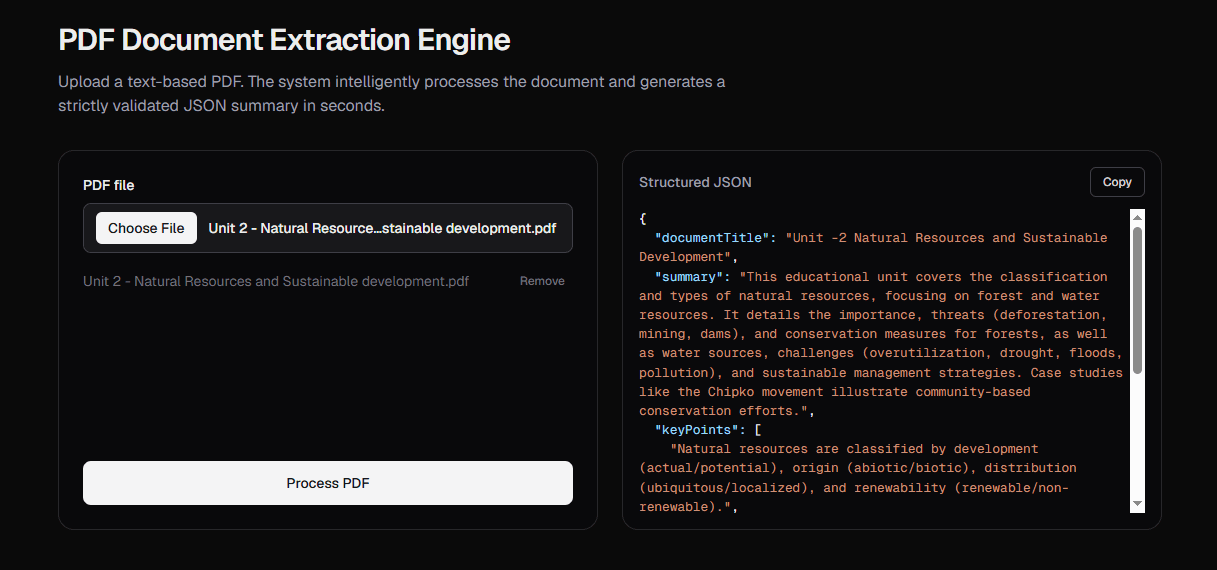
This production-ready Next.js boilerplate solves the hardest parts of document ingestion out of the box. Using a custom Map-Reduce architecture, it intelligently chunks massive PDFs, processes them sequentially, and outputs strictly validated JSON summaries in seconds.
What You Get:
Full Next.js App Router Source Code: Clean, modern, and heavily optimized.
Infinite-Length Chunking System: Process massive PDFs without crashing your server or hitting LLM output walls.
Universal AI Support: Pre-configured with the Vercel AI SDK to easily swap between OpenAI, Gemini, Anthropic, or OpenRouter.
Optimized Zod Schemas: Pre-built for blazing-fast lightweight extraction, completely ready for you to customize with your own business logic.
Built-in Telemetry: Development console logs track exact chunk counts and API latency so you can monitor pipeline performance.
Who is this for?
Founders and developers building AI SaaS, RAG applications, or internal data tools who want to skip 30+ hours of complex AI infrastructure setup.
Reviews
No reviews yet. Purchase to leave a review.